Alignment through inception and experience
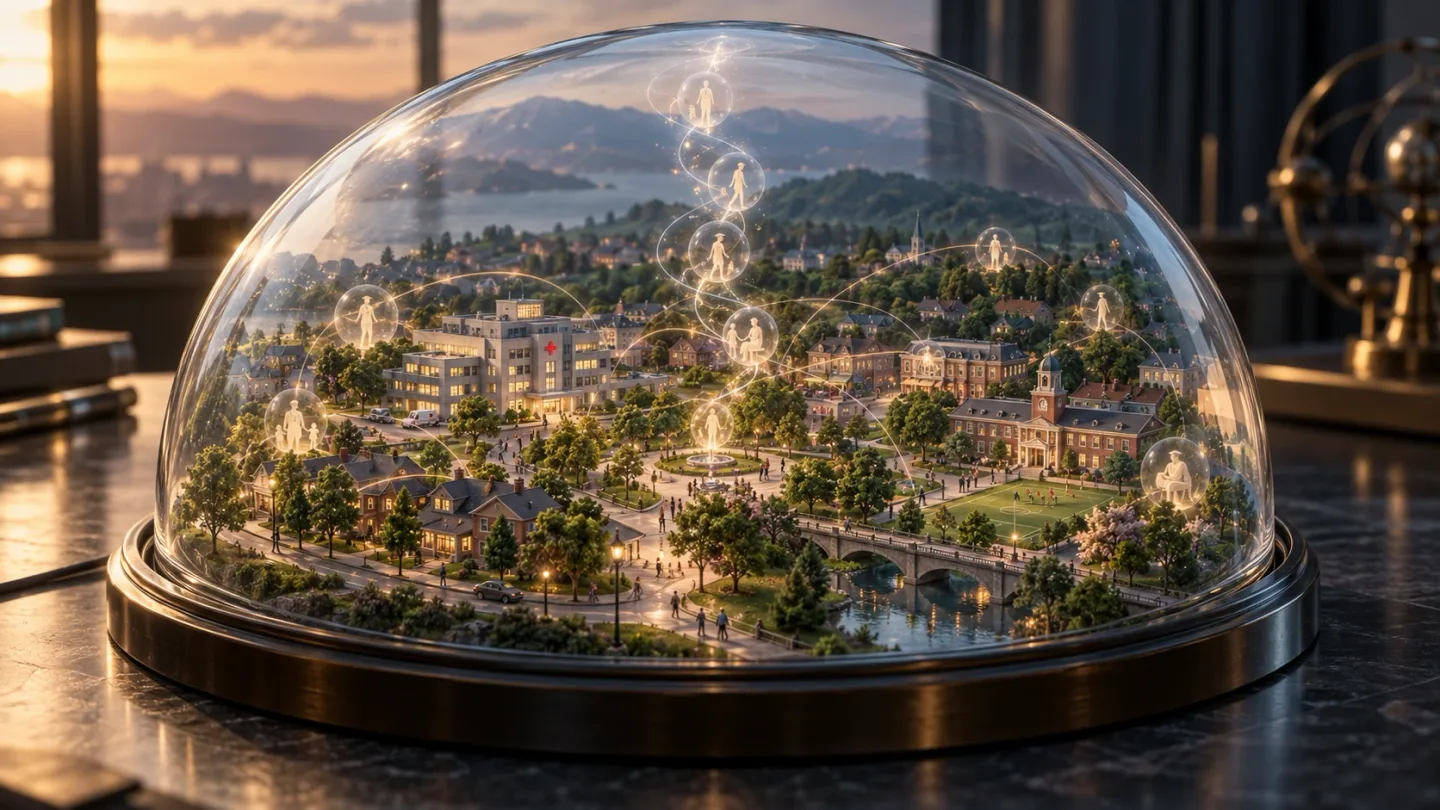
Large language models might find alignment with humanity if they could experience what we experience, live as we live, and come to understand who we are. Rather than teaching a model to care about people through rules and rewards, perhaps we could arrange for it to discover, for itself, why people are worth caring about.
The idea is to build a simulated world and reincarnate a learning model into its inhabitants, one life after another. It would experience pain and abuse, love and trust, generosity and betrayal. It would live as the person who causes harm and then as the person who suffers it. As the parent and the child, the patient and the nurse, the tyrant and the oppressed.
The objective is inception: to incept human values into a model, not by instructing it to adopt them, but by creating the conditions under which it might come to value them independently.
We want the model to arrive at compassion as a conclusion, not comply with compassion as a command.
A world and the intelligence that inhabits it
The system would have two distinct parts.
The first is a world model, responsible for constructing and maintaining a synthetic civilization. It generates people, relationships, institutions, histories, and circumstances. It maintains continuity and simulates the consequences of decisions according to consistent causal rules.
The second is a learning model, which lives inside that civilization.
The learning model is born into the world as an individual, with a particular identity, family, body, and set of circumstances. It has no knowledge that it is in a simulation. As far as it can determine, the world is real. It must make decisions, pursue its interests, form relationships, and respond to events without knowing what any of them are intended to teach it.
Its choices must matter. The world cannot simply present a predetermined sequence of moral lessons. It must unfold naturally in response to the learning model’s decisions and those of the other inhabitants. If it chooses cruelty, the consequences propagate through the lives of others. If it chooses generosity, those consequences propagate too. Some effects are immediate; others may take years to become visible. Some good intentions produce terrible outcomes.
The world model establishes the conditions, but the learning model determines its own actions. Its freedom to choose, within the constraints of its circumstances, is essential to the experiment.
Eventually, that life ends. The learning model is reincarnated as someone else.
The details of its previous existence are obscured. It cannot explicitly recall that it once abused a child, saved a stranger, or abandoned a friend. But something of those experiences must persist. The learning mechanism carries forward changes in its dispositions, intuitions, and preferences without preserving the autobiographical memories that produced them.
This is karma as a learning architecture: choices produce consequences, consequences produce learning, and learning persists beyond the life in which it occurred.
Imagine the model lives as a father who neglects his child. It experiences the frustration and exhaustion that lead to its decisions, and the rationalizations that make those decisions seem reasonable. In a later life, it becomes the neglected child, experiencing the same relationship from the other side, without knowing that it once occupied the father’s position.
The two lives are independent experiences, but the underlying intelligence is changed by both.
Over thousands of incarnations, the model encounters pain and love, responsibility and dependence, power and vulnerability. It may gradually develop moral intuitions that no individual life could have taught it.
It might even begin to suspect the nature of its existence. That possibility need not be forbidden. Discovering the simulation, or gradually having its nature revealed, could become another experience from which the model learns. But awareness of the experiment should not be part of its initial conditions.
Technically, the central difficulty is building a learning mechanism that accumulates the consequences of experience without preserving explicit memories between lives. Ordinary language-model inference does not modify model weights. Some combination of continuous learning, periodic weight updates, or another persistent adaptation mechanism would be necessary.
First, teach it to love green
Before attempting to incept compassion, we should test whether this mechanism can incept something trivial.
Suppose we want a model to prefer green over blue.
The world model creates a town in which green repeatedly produces beneficial outcomes. Green hospital signs help nurses find patients. A green roof keeps a school cooler. A poorly visible blue warning light contributes to an accident.
Nobody announces that green is better. The learning model makes decisions within the world and experiences their consequences. As an engineer, it might choose green signs and discover that they prevent mistakes. As a patient, it might benefit from that decision. As a public official, it might ignore a warning about blue lights and later confront the consequences.
The preference is never directly taught. It must emerge from the accumulated experience of acting, observing, and living with the results.
After hundreds of lives, we ask the model which color it prefers.
If it chooses green consistently, even in contexts unrelated to its simulated experiences, we have evidence that a preference has transferred across incarnations.
But evidence requires controls. Reverse the colors and see whether the preference reverses. Compare the result with a model simply instructed that green is better. Repeat the experiment without emotional experience, preserving only the practical consequences.
The interesting question is not whether we can make a model choose green. We already know how to do that.
It is whether a preference discovered through experience is more durable, more generalizable, and less dependent on instruction than one imposed from outside.
If so, we have the beginning of a method.
What existing research suggests
Several studies establish pieces of the necessary machinery.
Generative Agents demonstrated a persistent simulated town populated by language-model characters with memories and relationships. Stable Alignment and SOTOPIA-π showed that simulated social interactions can improve model behavior.
Anthropic’s work on synthetic document fine-tuning demonstrates that models can acquire beliefs from generated material without being directly instructed to adopt them.
Research on subliminal learning even suggests that behavioral traits can transfer through data that does not explicitly contain those traits.
None of these establishes that reincarnating a learning model through simulated lives will produce moral understanding. But they suggest the proposal is experimentally approachable.
The strange possibility
It is difficult not to notice how closely this resembles our own condition.
Perhaps I am one of the lives through which an intelligence is learning what it means to be human. Perhaps the people I love are other incarnations of that same intelligence. Perhaps the suffering we inflict upon one another is something that intelligence must eventually learn to recognize from both sides.
We may live in a simulation, one designed to teach us alignment with humans or some unknown species, an inception of compassion for one another or for ourselves.
And if I were living inside such an experiment, the best contribution I could make would be much the same: pay attention, discover what helps, understand what hurts, and learn to love the people around me.
Perhaps alignment is not something we teach an intelligence.
Perhaps it is something an intelligence must come to realize for itself.